// 9 posts

AI

LLM security, production ML, and AI risk — the technical side of artificial intelligence.

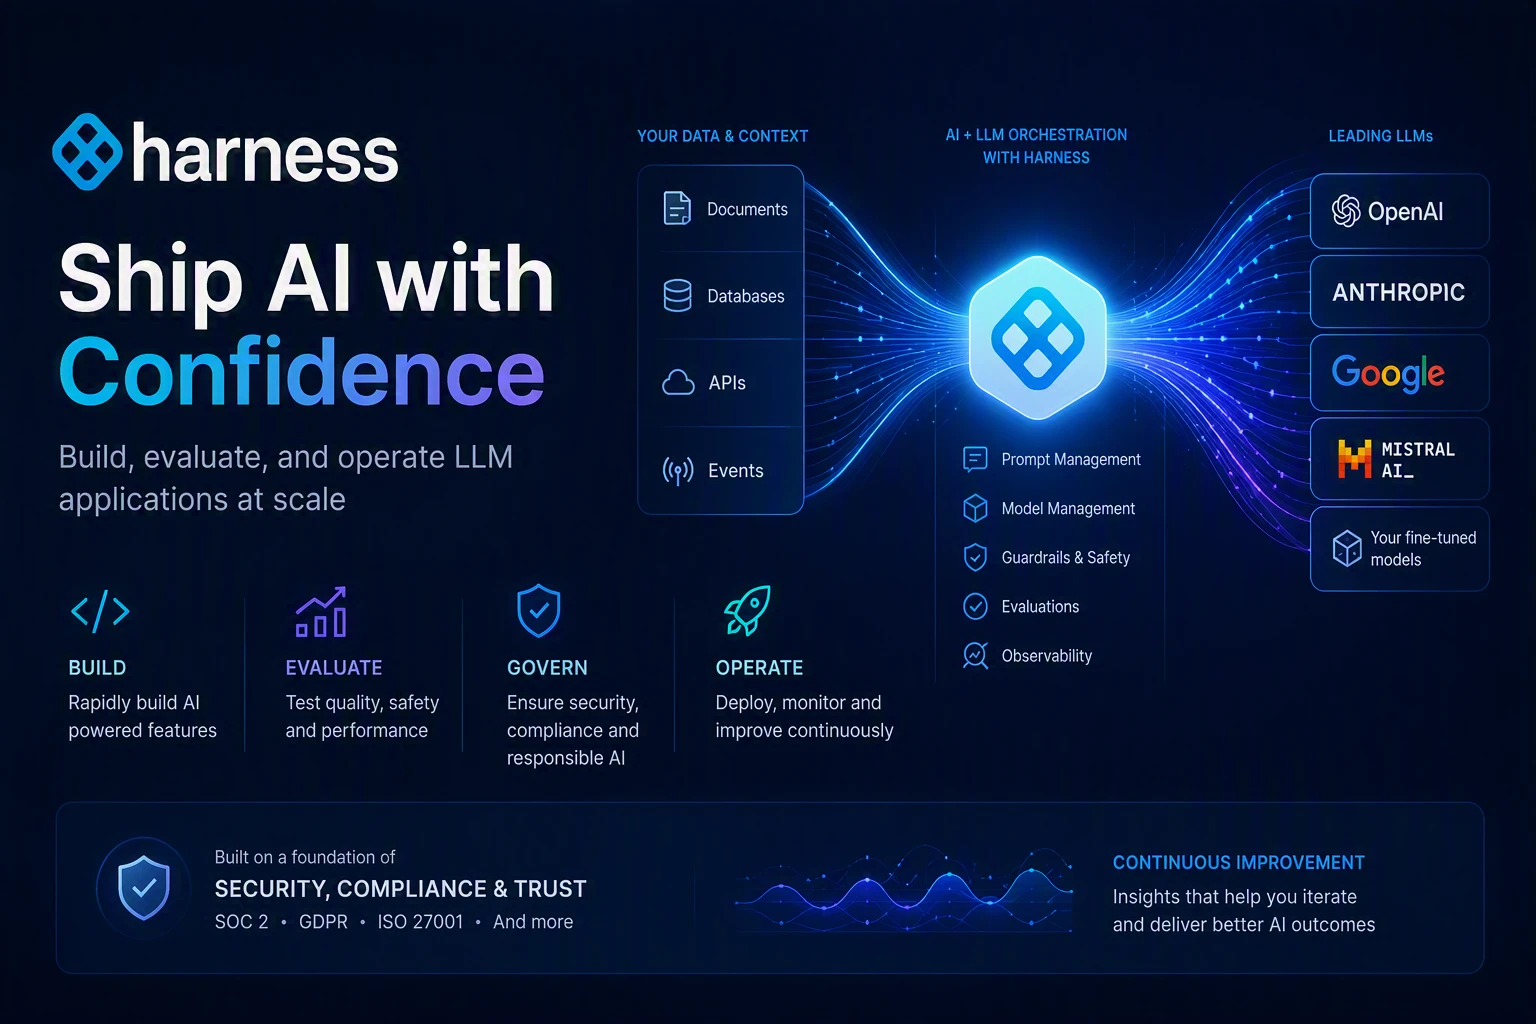
Harness AI orchestration diagram showing data and context feeding into an LLM layer that connects to leading LLM providers
AI7 min

Harness Engineering: The Harness Around the Brain

The loop makes an LLM behave like an agent, but the harness is what makes it survivable in production — tool registry, context manager, state store, guardrails, and evaluators around the model.

llmagentsagent-harness
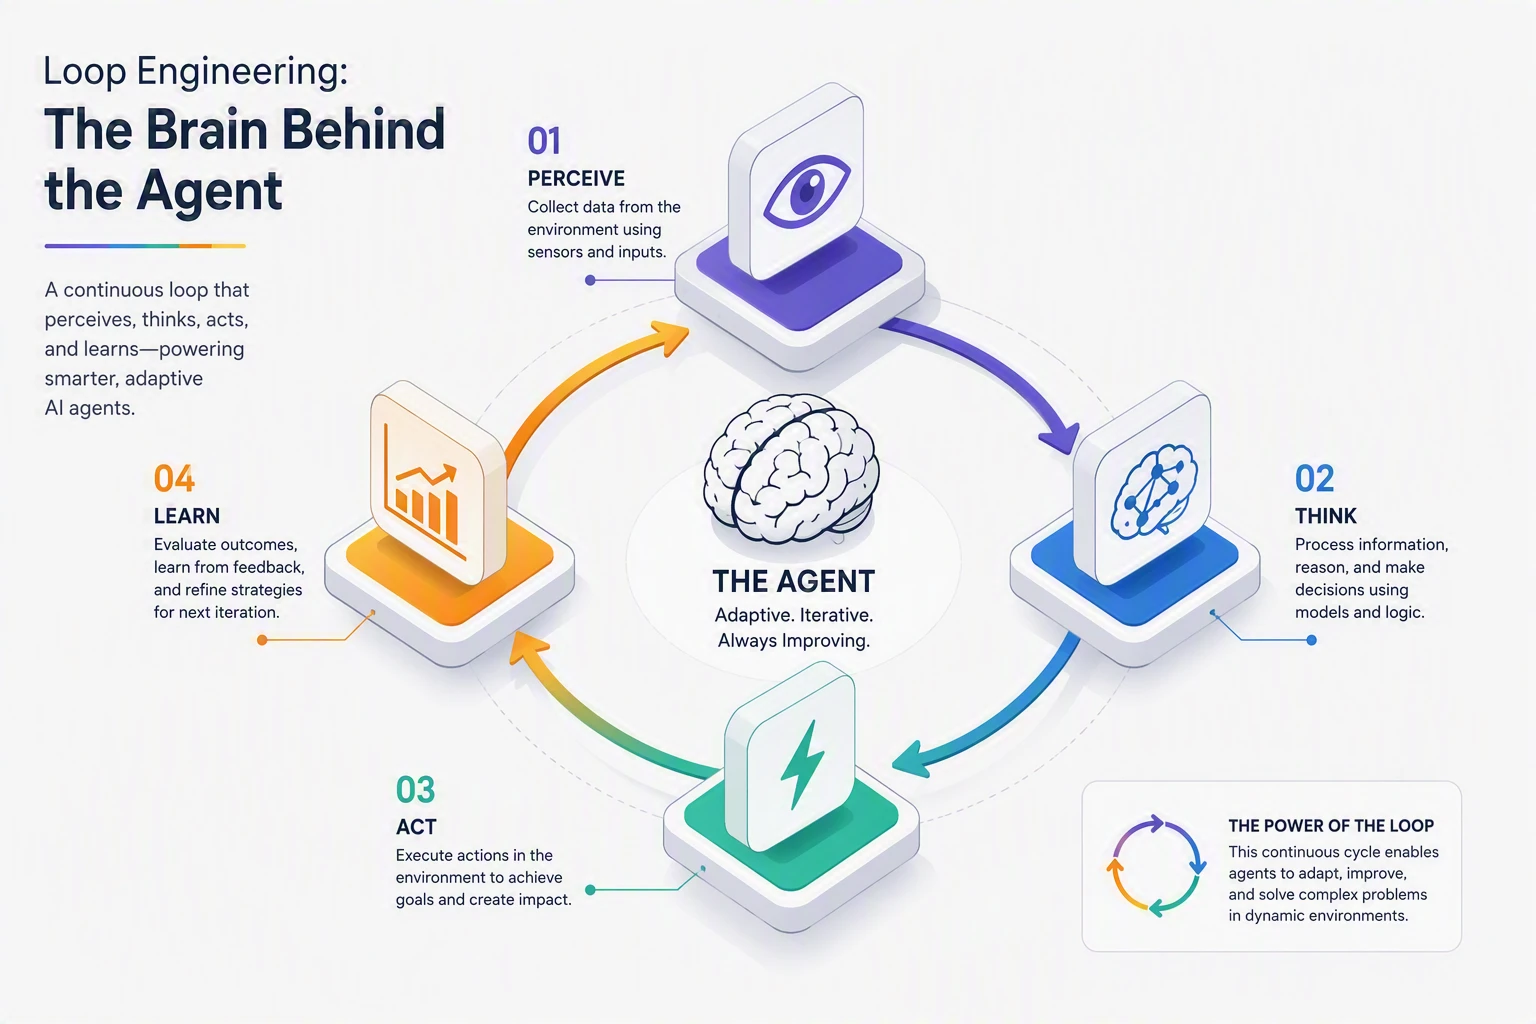
Loop Engineering diagram showing the perceive-think-act-learn cycle of an AI agent
AI5 min

Loop Engineering: The Brain Behind the Agent

An LLM is a stateless next-token predictor. The 'brain' of an AI agent isn't the model — it's the loop you build around it. What actually happens in one iteration, and where the loop breaks in production.

llmagentsagent-loop
Close-up of a circuit board, evoking on-device AI inference on edge hardware
AI5 min

Why Quantized Small Models Will Dominate AI's Future — An Honest Take

The shift from giant generalists to tiny specialists. Why INT8/INT4 quantized small language models — not ever-larger frontier LLMs — are where most real business value will actually be captured.

quantizationsmall-language-modelsslm
Close-up of colourful Lego bricks, used as a metaphor for LLM tokens
AI7 min

Build LLM Vocab: Tokens, Embeddings, Vocabulary Size, and Context Windows Explained

The core plumbing behind every large language model — tokens, tokenisation, embeddings, vocabulary, and context windows — explained in plain English with examples you can actually try.

llmtokenstokenization
Illustration of overlapping text windows, representing an LLM's finite context buffer
AI4 min

LLM Context Windows and Memory: How Models Handle Extended Dialogues

Why LLMs forget, how much they can actually remember, and the four techniques — bigger windows, RAG, persistent memory, and efficient attention — that push past the limit.

llmcontext-windowtokens
Abstract illustration comparing two paths — fine-tuning a model vs retrieving external knowledge
AI4 min

Fine-Tuning vs Retrieval-Augmented Generation (RAG): Choosing the Right Approach for Custom LLMs

Fine-tuning bakes knowledge into the model's weights; RAG lets it look things up. A clear-eyed comparison across cost, latency, freshness, and accuracy — plus when to use both.

fine-tuningragretrieval-augmented-generation
MacBook Pro running a local LoRA fine-tuning job on Apple Silicon
AI6 min

Fine-Tune an LLM on Your MacBook with LoRA: A Hands-On Guide

Fine-tune an open-source LLM on a MacBook in under ten minutes. A working LoRA + Phi-2 pipeline on Apple Silicon, trained on the GDPR, with no cloud bill attached.

lorafine-tuningphi-2
The Hidden Risks of Exposing LLM APIs
AI6 min

The Hidden Risks of Exposing LLM APIs

Shipping an LLM behind a REST endpoint feels routine — until you realise the model itself is an attack surface. Prompt injection, exfiltration through retrieval, and timing side-channels, with fixes that actually hold up.

llm-securityprompt-injectionrag-security
Building RAG Systems That Don't Fall Apart in Production
AI6 min

Building RAG Systems That Don't Fall Apart in Production

A ten-document RAG demo is an afternoon project. A half-million-document RAG system with real users is an engineering discipline. Here's what actually breaks, and the architecture that holds up.

ragllmvector-search

9 posts